How to Evaluate AI Writing Output Quality Before You Publish
If you want to know whether AI writing is fit to publish, use How to evaluate AI writing output quality before you publish as the test: judge it on four…
How to Evaluate AI Writing Output Quality Before You Publish
Last updated: October 12, 2026
Key Takeaways
- If even one check fails, revise the piece before it goes live.
- I review it in four passes: facts, reader value, voice, and risk.
- I would score AI writing on five parts: accuracy, completeness, usefulness, tone, and safety, with accuracy weighted highest.
- If the draft is accurate but bland, tighten the angle, add one concrete example, and remove repetition.
If you want to know whether AI writing is fit to publish, use How to evaluate AI writing output quality before you publish as the test: judge it on four things—accuracy, usefulness, voice, and risk. Everything else is secondary. A draft can sound polished and still be wrong, thin, or unsafe to post, so a quick “sounds human” check is not enough; consult a professional or source-backed editor when the topic is sensitive. For a practical benchmark, many editorial teams aim to resolve factual issues before publication, because content errors can erode trust quickly.
What actually determines whether AI writing is publishable?
Publish it only if the draft answers the reader’s question correctly, says something useful in the first 150 words, matches your brand voice, and does not create legal, factual, or reputational risk. If even one of those fails, the draft needs work before it goes live.
The mistake I see most often is treating “sounds human” as the finish line. That is not the same as being ready to publish. A clean sentence can still contain a wrong claim, a vague recommendation, or a hidden contradiction, so consult a professional when the stakes are high and verify against a reliable source such as the FTC, NHS, CDC, SEC, APA, ISO, or the relevant government agency. The safer test is to score the piece against the job it needs to do.
Here is the simple filter I would use:
- Accuracy: Are the facts, names, dates, and definitions right?
- Specific usefulness: Does it help a reader do something, decide something, or understand something they could not already infer?
- Voice fit: Does it sound like your publication, not like a generic assistant?
- Risk: Could this create harm if posted as-is, especially in health, finance, legal, safety, or regulated topics?
If the piece is meant for a blog post about a low-stakes topic, a few rough edges may be acceptable. If it is customer-facing copy, a support piece, or content in a regulated space, the bar is higher. I would not publish anything in those categories unless the facts have been checked against primary sources and the wording has been stripped of any overclaiming.
A useful rule: if you cannot explain why this version is better than the top 3 search results, the draft is probably not ready. Quick check: if the draft is accurate but bland, or interesting but shaky, you still have work to do.
How do I evaluate AI writing output before I publish?
I evaluate it in four passes: fact check, reader-value check, voice check, and risk check. If the piece passes all four, I move it to final edit; if it fails any one pass, I revise or reject it.
Start with facts, because everything else sits on top of them. Check named entities, product details, policy claims, model names, and any “always,” “best,” or “guaranteed” language only when they matter to the claim and can be verified. For source-backed topics, compare the draft to primary or authoritative sources such as the FTC, NHS, CDC, SEC, APA, ISO, or the relevant government agency. If the draft makes a claim that needs evidence and you cannot trace it, remove it.
Then test usefulness. Ask: does this give the reader a next step, a comparison, a checklist, a decision rule, or a concrete example? A draft that only paraphrases the prompt is not useful. A paragraph that says “AI can save time” is not useful unless it explains where the time is saved, what trade-off appears, and what the reader should do next.
Then check voice. Read two paragraphs aloud. If every sentence could belong to any website in your niche, the draft lacks identity. Replace generic phrases with precise nouns and verbs. If your brand is plainspoken, cut the gloss. If your brand is technical, remove the hand-holding that makes the copy feel watered down.
Finally, check risk. This is where many “good” drafts fail. A piece can be factually decent and still be too absolute, too promotional, or too dismissive of edge cases. That matters in content that could affect money, health, legal rights, or safety. In those cases, I would rather publish a narrower piece that is clearly bounded than a broad one that overreaches.
A good working sequence:
- Read the piece once without editing.
- Mark every claim that would need proof.
- Check each claim against a reliable source or delete it.
- Highlight any sentence that sounds generic or inflated.
- Rewrite the opening so it answers the searcher’s question in the first 2 sentences.
- Run one final read for contradictions, missing steps, and risky absolutes.
If you want a fast screen, use a 10-minute triage: 3 minutes for facts, 3 for usefulness, 2 for voice, 2 for risk. With a source-backed checklist, that is often enough to catch the biggest problems before deeper editing, though a professional review may still be needed in high-stakes topics. Quick check: if you can point to the exact line that makes the piece worth publishing, you are close.
What score should I give AI writing quality?
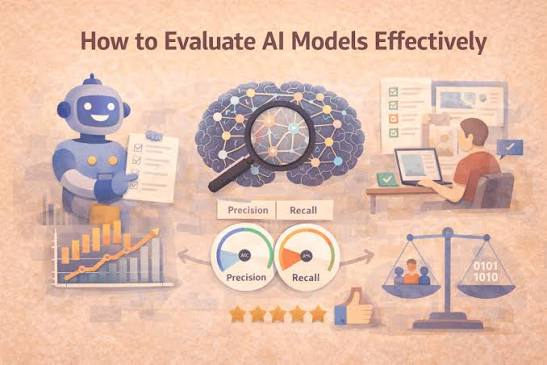
I would score AI writing on a 5-part rubric: accuracy, completeness, usefulness, tone, and safety, with accuracy carrying the most weight. If the accuracy score is low, the rest of the numbers do not matter.
A simple rubric keeps the review from turning into a vibe check. Score each category from 1 to 5:
- Accuracy: Are there errors or unverifiable claims?
- Completeness: Does it cover the reader’s decision or task end to end?
- Usefulness: Does it provide steps, criteria, examples, or distinctions?
- Tone: Does it match the intended audience and brand?
- Safety: Could this mislead, overpromise, or create compliance problems?
I would not use the same threshold for every type of content. A thought-leadership piece can survive a 4/5 in completeness if it has a sharp point and correct framing. A tutorial cannot; for step-by-step content, consult a subject expert if anything is missing. For procedural content, I want every step to be complete enough that a reader could follow it without guessing. For medical, legal, or financial topics, I want an even stricter screen and professional review where appropriate.
Here is a useful way to interpret the score:
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| Marketing piece | Publish only if accuracy and tone are 4/5 or better | A pretty piece with weak facts hurts trust |
| How-to guide | Publish only if completeness and accuracy are both strong | Missing one step breaks the whole instruction |
| Regulated topic | Hold for expert review even if the piece scores well | A high score does not remove legal or factual risk |
| Short product page | Prioritize tone, safety, and claim control | Long explanations can bury the offer |
If the piece gets 3/5 on accuracy, I stop there and fix facts first. If it gets 5/5 on accuracy but 2/5 on usefulness, I treat it as a rewrite, not a polish job, and I would still consult a professional if the topic affects decisions. A piece that merely sounds nice is not ready.
The one place I would resist over-scoring is creative copy. A tagline or brand poem may not fit a rigid rubric. Still, even there, I want to know whether the piece says something specific, distinctive, and on-brand. Quick check: if your scoring system cannot tell the difference between “serviceable” and “ready,” it is too vague to help.
If the piece is accurate but boring, what do I do?
If the piece is accurate but boring, I tighten the angle, add a concrete example, and cut any paragraph that repeats the same point in different words. Boring copy is usually a structure problem, not a word-choice problem.
This is the situation where many editors make the wrong move. They keep polishing sentences when the real issue is that the piece has no tension. Good writing for publication needs a reason to exist beyond “AI made a text.” The reader needs a payoff: a decision, a shortcut, a warning, a comparison, or a practical framework.
Next, try this sequence:
- Write the one-sentence promise the piece should make.
- Check whether the opening states that promise in plain language.
- Look for at least one concrete example, benchmark, standard, or tool name.
- Cut any paragraph that says the same thing as another paragraph.
- Add one conditional branch: “if X, do Y; if Z, do the opposite.”
- Replace abstract nouns with actions and outcomes.
For example, a weak line like “AI can improve productivity” should become something like “If the piece is for an FAQ page, ask whether it answers the customer’s top three questions in under 300 words; if it doesn’t, rewrite the structure, not the sentence.” The second version gives the reader a way to decide.
I would also watch for “flatter copy syndrome,” where every sentence is grammatically fine but nothing changes from one paragraph to the next. The fix is not more adjectives. It is more information density. Add a benchmark, a comparison, a limitation, or a warning.
This advice is not for lyrical brand writing or experimental essays. If the goal is mood rather than utility, a different standard applies. But for most web content, boring usually means under-specified. Quick check: if a reader could predict the next sentence, the piece needs a sharper angle.
When should I reject AI writing instead of editing it?
I reject AI writing instead of editing it when the draft is built on bad premises, contains unsupported claims that matter, or has the wrong structure for the job. If the foundation is weak, editing only burns time.
A piece should be rejected, not salvaged, when one of these is true:
- The central claim is false or too broad.
- The draft confuses the reader about what to do next.
- The structure is so repetitive that rewriting would be faster than fixing.
- The content touches regulated or high-stakes decisions without proper sourcing.
- The voice is so generic that it cannot reasonably be made distinctive without a full rewrite.
This is where people waste the most time. They spend 45 minutes polishing a draft that should have been scrapped after 5. I would rather throw out a mediocre 800-word draft than force it into shape and publish a weak piece with a prettier surface.
A rejection decision also protects the publication standard. If you keep editing every draft, the model learns that almost anything is acceptable with enough polish. That is how quality slides. A stronger rule is to reserve editing for drafts that already have the right answer, the right angle, and at least the beginning of a useful structure.
Use a hard stop if you find any of these:
- The draft invents examples or evidence.
- It gives advice without conditions.
- It hedges so much that the recommendation disappears.
- It claims certainty where the topic demands caution.
- It is optimized for length rather than reader value.
If you are deciding between “fix” and “reject,” ask whether the piece would still be worth reading if you removed every flashy sentence. If the answer is no, reject it.
A practical threshold helps here: if more than a third of the piece needs structural rewriting, I would treat it as a new draft rather than an edit. Quick check: if you keep saying “I can save this,” but cannot name the core reason it deserves publication, let it go.
What are the edge cases that break the normal rules?
The normal rules break down when the piece is short, regulated, highly technical, translated, or intended for a nonstandard format. In those cases, the criteria shift, and a plain readability check is not enough.
However, here are the cases I would treat differently:
-
Situation: Very short copy, like meta descriptions or headlines.
What changes: There is no room for full explanation, so every word must earn its place.
What to do instead: Check for accuracy, intent match, and specificity. A 155-character meta description that is vague is worse than a longer one that is clear. -
Situation: Regulated topics, such as health, finance, law, or safety.
What changes: Claims carry higher downside, and a polished tone can hide weak sourcing.
What to do instead: Verify against authoritative bodies and route the piece for expert review. For medical or legal content, a professional consultation hedge may be appropriate. -
Situation: Technical documentation or SOPs.
What changes: “Good writing” means unambiguous instructions, not style.
What to do instead: Test for sequence, missing prerequisites, and failure states. A single skipped step can make the document unusable. -
Situation: Localization or translation drafts.
What changes: Literal accuracy is not enough if the phrasing sounds unnatural in the target language.
What to do instead: Review for idioms, examples, units, dates, and cultural fit. The piece should read like it was written for that market, not translated into it. -
Situation: Opinion pieces or brand voice content.
What changes: Exact factual density matters less than distinct position and consistent voice.
What to do instead: Ask whether the piece takes a clear stance and avoids flat, interchangeable language. -
Situation: Content built from multiple sources.
What changes: Contradictions become more likely.
What to do instead: Check for scope drift, conflicting definitions, and inconsistent recommendations before publication.
I would not use the same publish/no-publish threshold for every one of these. The more the piece can affect decisions, compliance, or safety, the stricter I get. Quick check: if the format has tight space, high stakes, or translation risk, the usual “does it read well?” test is too shallow.
A practical pre-publish workflow that actually works
If you want one workflow to follow, use a 3-pass review: factual, structural, then final-risk. That sequence catches most bad pieces faster than line editing from top to bottom.
Here is the order I would use:
- Pass 1: Facts. Mark every claim, number, name, and promise. Verify against reliable sources or remove it.
- Pass 2: Structure. Check whether the piece answers the main question in the first paragraph, covers the reader’s decision path, and avoids repetition.
- Pass 3: Risk. Look for absolutes, omissions, compliance issues, and anything that could mislead a reader if published today.
- Pass 4: Final read. Read the piece aloud once to catch awkward phrasing and missing transitions.
That workflow works best when you keep the same standard from start to finish. A source check should come before style cleanup, because a smooth sentence cannot rescue a wrong one. For broader guidance on trustworthy content, see the FTC’s consumer advice on misleading claims, the NIH’s plain-language resources, and Google Search Central’s advice on helpful content: FTC, NIH, and Google Search Central.
If a piece clears those passes, I still do one last consistency check. Look for date drift, duplicate claims, and anything that sounds inflated. Quick check: if the piece still feels uncertain after the final read, it is not ready.
A few practical numbers that help
A useful standard is to inspect the first 150 words for clarity, because that is where readers decide whether to continue. In short-form copy, a 155-character meta description gives you very little room, so even one vague phrase can weaken the piece.
For editorial triage, 10 minutes is enough to catch many obvious issues: 3 minutes for facts, 3 for usefulness, 2 for voice, and 2 for risk. On longer pieces, a 45-minute polish pass is often wasted if the structure is wrong, so it is better to catch those problems early than to rewrite them late.
If the content is regulated, technical, or customer-facing, the threshold should be stricter than for a casual blog post. That does not mean every piece needs a formal review board, but it does mean the review process should match the stakes.
Final rule of thumb
Ultimately, evaluate the piece the way a careful editor would: verify the facts, judge the usefulness, check the voice, and measure the risk. If a piece passes those tests, it is ready to publish; if not, it needs more work.
The simplest test is still the best one: would you stand behind this piece if a reader quoted it back to you? If the answer is no, keep editing until the answer becomes yes.
Drafted with AI; not yet reviewed by a person.